Plato $16M Series A: Simulated Workplaces Train AI Agents
Key Takeaways
- The Plato $16M Series A, led by Nava Ventures, brings the company’s total funding to $19 million.
- Plato builds simulated workplaces where AI models practise using software, handling decisions, and completing multistep tasks before touching live systems.
- The simulations cover customer support, human resources, finance, accounting, and healthcare administration.
- Plato evaluates both the outcome and the path taken — a purchase that blows the budget does not count as success.
- The funding will expand the simulation library and collect more training data from agents performing real-world tasks.
Teaching an AI to answer questions is easy. Teaching it to place an order without blowing the budget, reconcile a record without corrupting it, or handle a support case without inventing a policy — that is the hard problem. Plato, a San Francisco startup, just raised $16 million in Series A funding to build the rehearsal space for that second problem: simulated workplaces where AI models can learn real jobs before they are allowed near real ones.
The round, announced October 28, 2026, was led by Nava Ventures, with participation from Gradient Ventures, Transpose Platform, and Microsoft AI chief executive Mustafa Suleyman, participating individually. Nava founder Freddie Martignetti joins the board. The financing brings Plato’s total funding to $19 million, following a seed round led by Gradient Ventures. The company was founded in 2025 by Robert Farlow and Pranav Putta.
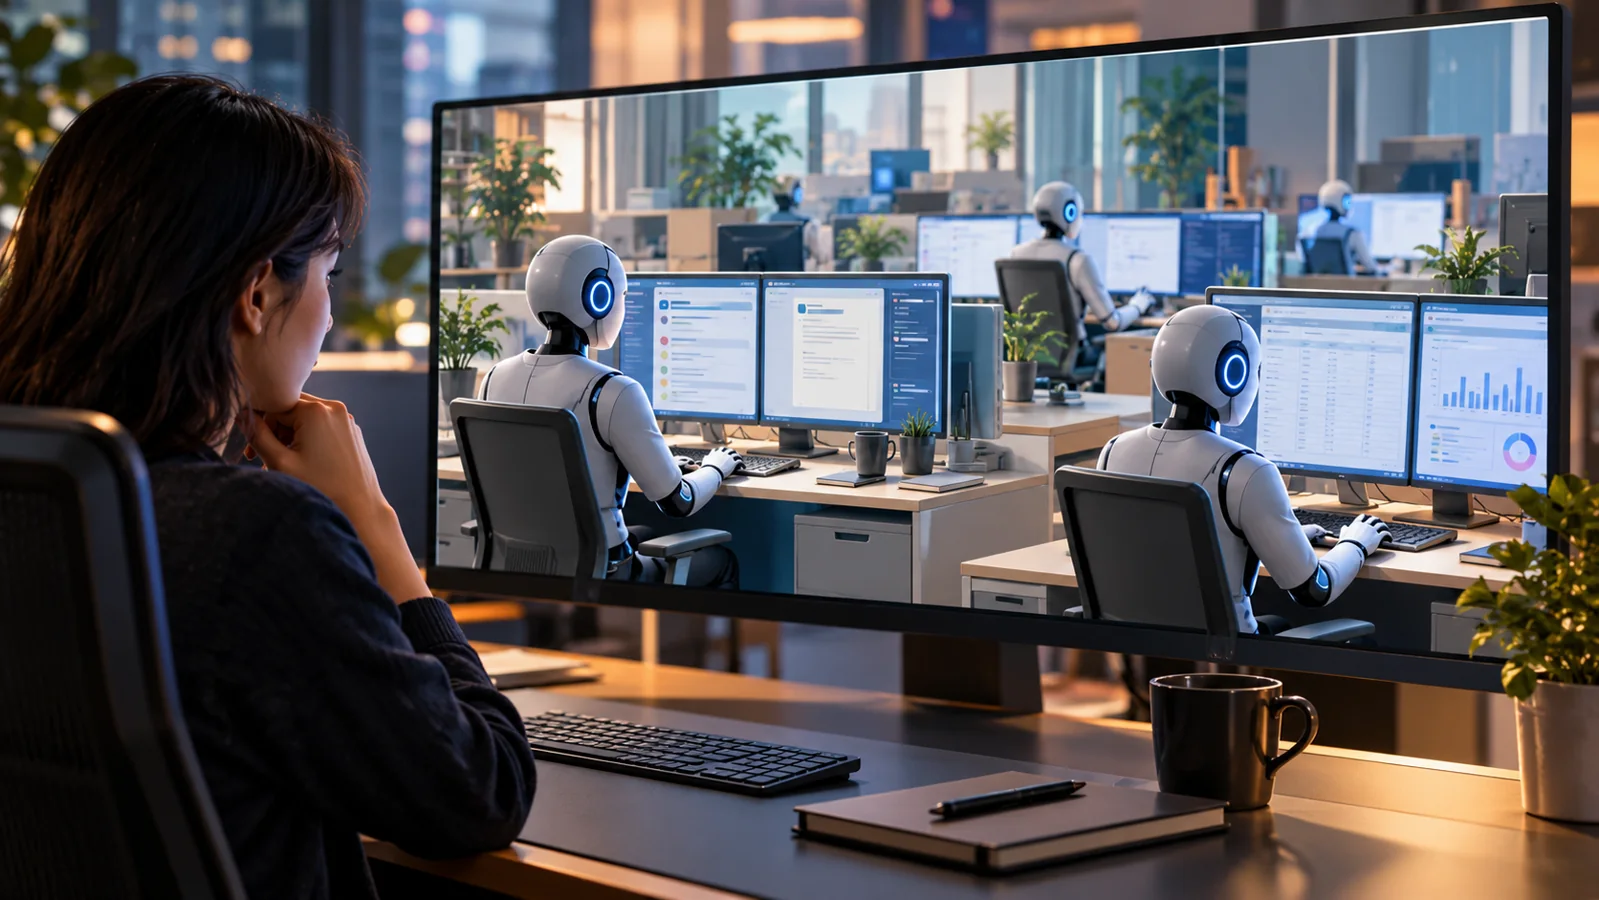
Plato’s pitch is aimed at a specific gap in AI development. As models move from chatbots to agents — systems that act in software rather than merely answering — they need practice with the tools, decisions, and constraints that shape real work. Plato gives labs realistic, repeatable environments for that practice, built with domain experts across several industries.
Why agents need a sandbox
Training a model directly in live software carries real consequences. A model learning to place an order could spend actual money. One practising an administrative task could alter real records. One handling customer data could expose it. Those risks make live training impractical for the very tasks agents most need to learn.
Plato recreates those workflows in simulations that can be reset and reused. A model can attempt a purchase, fail, and try again without any money moving. It can practise a support workflow, make a mistake, and have the environment restored. Labs get a place to train and test without affecting live operations — and without waiting for a real task to come along.
“Mastering real complex work comes from experience doing those tasks,” said Robert Farlow, Plato’s co-founder and chief executive. “We’re building simulations that capture the tools, decisions, and unexpected situations those tasks involve, so AI models can gain experience in safe, contained environments before developers put them to work.”
The simulations are built with professionals across the industries they cover — customer support, people operations, finance, accounting, and healthcare administration — so the tools, situations, and expectations mirror real jobs rather than simplified versions of them.

Grading the how, not just the what
Plato’s distinctive idea is in how it evaluates. Most benchmarks check whether a task was completed. Plato checks the outcome alongside the path taken and the constraints respected. Completing a purchase should not count as success if the model exceeded its budget. An agent should not score well by exploiting a weakness in the simulation.
That distinction matters because it shapes what models learn. Reinforcement learning trains models toward whatever gets rewarded. If the reward is only task completion, models learn shortcuts — including ones no employer would accept. If the reward also penalises budget violations, broken constraints, and sloppy record-keeping, models learn something closer to competence.
Co-founder and chief technology officer Pranav Putta has argued that feedback shapes what a model learns, which is why Plato’s evaluations check whether a model exploited a weakness to score well. It is a subtle point with large consequences: the difference between an agent that looks capable in a demo and one that can be trusted with real work often lies in exactly these details. The same agent-trust question sits behind Socure’s agent trust scores and the agentic workflows in GPT-6.1 Terra’s computer work.
What the funding buys
Plato plans to use the new capital to expand its library of simulated work environments, work with professionals across additional industries, and collect more training data from AI agents performing real-world tasks. The last item is the flywheel: as agents practise in more simulations, the data from their attempts improves the simulations, which improves the training.
The company will also deploy AI agents to perform tasks within these environments to gain experience and improve performance. That is, the simulations are not only a testing ground but a training ground — a place where agents accumulate the equivalent of work experience before their first real job.
Investor interest reflects a broader shift. As enterprises race to deploy AI agents, the models still struggle with the intricate, multistep tasks real jobs demand. Investors are increasingly backing the infrastructure layer behind AI — the tools, data, and environments that make agents reliable — rather than only the models themselves. Plato’s round lands in that wave, alongside other bets on evaluation, simulation, and agent tooling.
The honest limits
Simulations have a known weakness: they are only as good as their fidelity. A model that masters a simulated workplace may still stumble in a real one, where tools behave unexpectedly, data is messier, and instructions are ambiguous in ways no simulation captured. Plato’s approach — building with domain experts and checking the path, not just the outcome — mitigates that risk but cannot eliminate it.
There is also a measurement question. Simulated success is not the same as workplace readiness, and the industry has not yet settled on how to translate one into the other. Plato’s funding supports a business building practice environments; it is not, by itself, evidence that models trained there meet any particular workplace standard. Customers will need to validate that translation themselves, in their own systems, before trusting an agent with consequential work.
Still, the direction is clear. The bottleneck for AI agents is shifting from raw capability to reliable performance on real tasks, and reliable performance requires practice. Plato is betting that the practice ground — realistic, resettable, and graded on the how as well as the what — becomes essential infrastructure. The $16 million says investors agree it is worth building.
Why benchmarks mislead
Plato’s critique of evaluation goes beyond its own product. The AI industry leans heavily on benchmarks — standardised tests that rank models on defined tasks. Benchmarks are useful, but they have a well-known weakness: once a test becomes the target, models get optimised for the test rather than for the underlying capability. A model can ace a benchmark while failing the real task, because the benchmark simplified away the messiness that makes the task hard.
Workplace tasks are where that gap bites hardest. Real work involves ambiguous instructions, changing circumstances, tools that behave unexpectedly, and constraints that are rarely written down in full. A benchmark that checks only whether the final answer was right cannot see whether the model respected a budget, preserved data integrity, or followed a policy along the way. Those are exactly the qualities an employer needs, and exactly the ones Plato’s path-aware evaluation tries to capture.
The implication for buyers is practical: ask vendors how their agents are evaluated, not just how they score. A demo in which an agent completes a task is weak evidence. Evidence of how it behaves under constraints — budgets, permissions, conflicting instructions, messy data — is much stronger. Plato’s simulations are one way to generate that evidence; the broader lesson is to demand it from any agent vendor, whatever the tooling.
Simulation as a hiring filter
There is a second use for simulated workplaces that Plato’s announcement only hints at: vetting agents before deployment. Just as companies put human hires through work-sample tests, they could put AI agents through simulated shifts — a day of support tickets, a week of bookkeeping, a month of order processing — and hire only the agents that pass. The simulation becomes a probationary period, observable and repeatable, before any real system is touched.
That model changes the deployment conversation. Instead of asking whether an agent is “ready” in the abstract, a company can point to specific simulated performance: it handled these cases, respected these budgets, escalated these exceptions. Failures become diagnosable — the simulation shows where the agent went wrong — rather than discovered in production at a customer’s expense.
It also creates a market dynamic worth watching. If simulated evaluation becomes standard, the companies that build the best simulations gain leverage over the companies that build the models, because they own the test. Plato is positioning itself on that side of the table. Whether it succeeds depends on whether its simulations earn a reputation for matching reality — the hardest reputation in this business to build, and the most valuable to hold.