What Is RAG? How AI Answers From Your Own Documents
Key Takeaways
- RAG — retrieval-augmented generation — means the AI first retrieves relevant passages from your own documents, then generates an answer grounded in those passages.
- The pipeline is: ingest and chunk your documents, turn each chunk into a vector, store the vectors, and at question time retrieve the best-matching chunks and feed them to the model.
- RAG helps when the answer lives in your documents and changes often. It fails when documents are stale, chunking breaks context, or the retriever returns plausible-but-wrong passages.
- RAG reduces hallucination; it does not eliminate it. The model can still misread retrieved text or go beyond it.
- Most production RAG failures trace to retrieval quality, not to the model’s writing ability — so fix retrieval before you upgrade the model.
Ask an AI chatbot a question about your own company, your own handbook or your own product documentation, and it will either guess or tell you it does not know. That is not a flaw in the model; it is a missing ingredient. The model was never given your documents. Retrieval-augmented generation, universally shortened to RAG, is the standard way to supply them: retrieve the relevant passages first, then generate the answer from what was retrieved.
What RAG actually does, in plain English
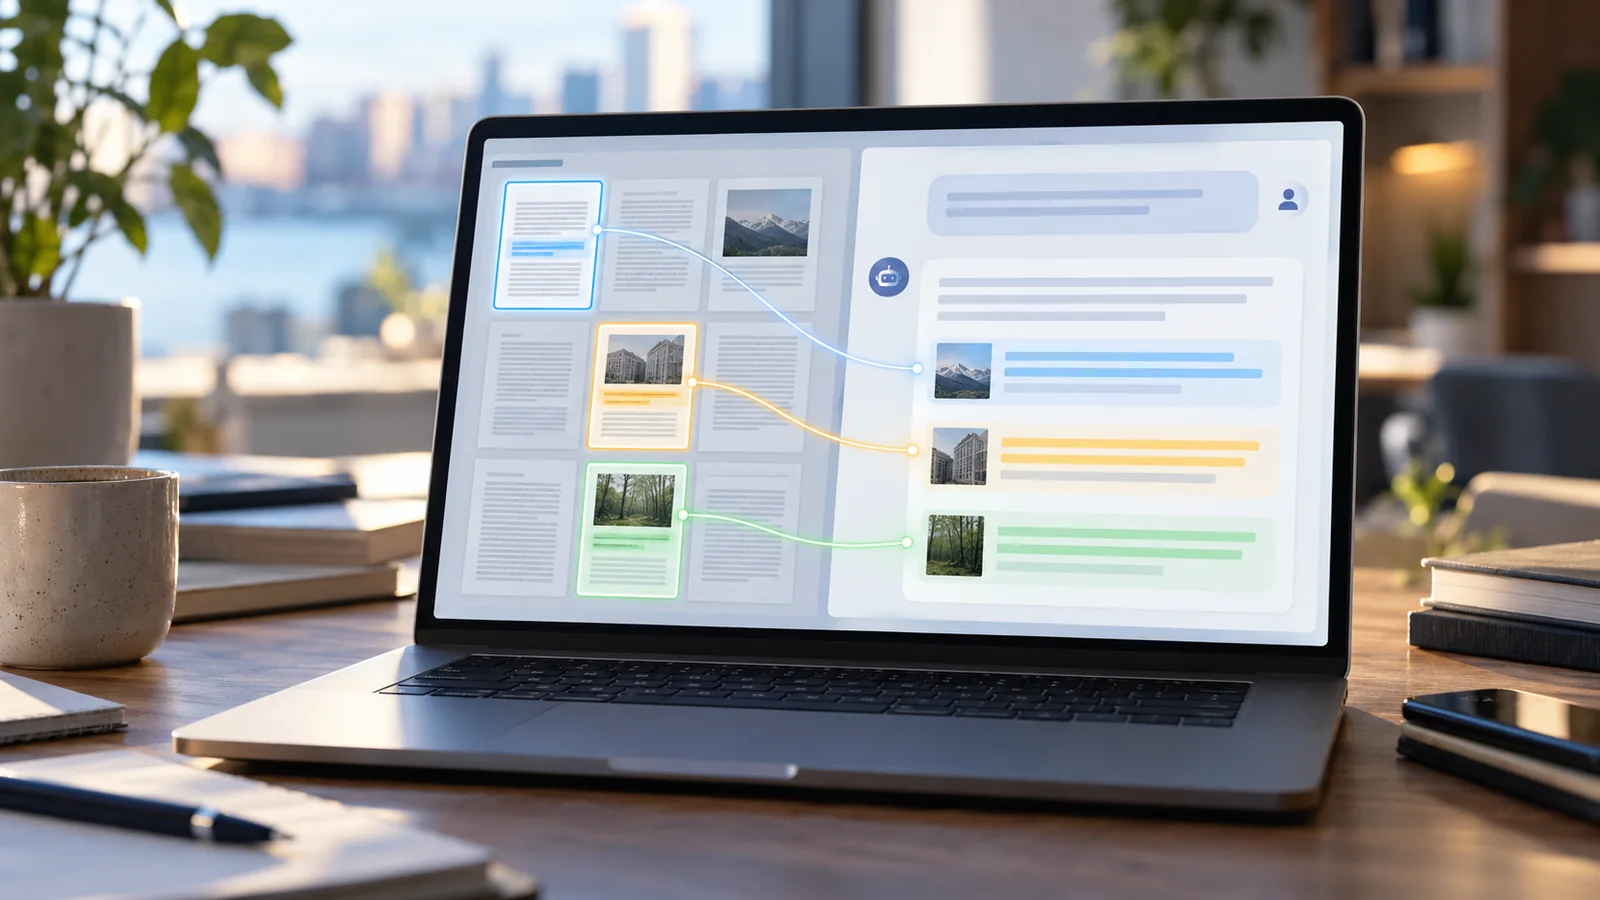
Imagine a very fast librarian. You ask a question. The librarian does not answer from memory; instead, she runs to the shelves, finds the pages most relevant to your question, brings them back, and hands them to an expert with a note: “Answer using these pages, and say which page each part came from.” The expert’s answer is only as good as the pages the librarian brought. That is RAG, almost exactly.
The technique was described by Lewis and colleagues at Meta AI Research in a 2020 paper, and it has since become the default architecture for question-answering over private or changing knowledge: company wikis, support documentation, legal files, medical references. Wherever the answer must come from your documents rather than from the model’s training data, RAG is the first approach worth considering.
How the pipeline works, step by step
- Ingest. Collect the documents: PDFs, wiki pages, support articles, spreadsheets. Note each document’s source, access level and last-modified date, because all three matter later.
- Chunk. Split each document into passages. Guides commonly cite chunks of roughly 200 to 1,024 tokens, often split by paragraph or section with some overlap so a thought split across a boundary is not lost. Chunking is the step most beginners rush, and it is the step that most often breaks retrieval.
- Embed. Turn each chunk into a vector — a list of numbers that captures its meaning — using an embedding model. Similar meanings produce similar vectors, which is what makes the next step possible.
- Store. Put the vectors, plus their source text and metadata, into a vector database. The metadata is what lets you filter by access level or date later.
- Retrieve. When a question arrives, embed the question the same way, find the most similar chunks, and optionally improve the ranking: combine vector similarity with keyword matching (a hybrid search), or re-rank the top candidates with a second, more careful model.
- Generate. Insert the retrieved passages into the model’s prompt, with an instruction to answer from them and cite the source passages. The model writes the answer; the citations point back to your documents.
Two details matter more than they first appear. First, access control must be enforced at retrieval time, not at generation time: if a user is not allowed to see a document, its chunks must never reach the prompt, because anything in the prompt can leak into the answer. Second, freshness is a retrieval problem: if a document changes and the index is not updated, the system will confidently answer from the old version. Stale index, stale answer.
When RAG helps, and when it fails
| Situation | RAG helps? | Why |
|---|---|---|
| Answer lives in your private documents | Yes | The model cannot know what it was never trained on |
| Information changes often | Yes | Update the index, not the model |
| Answers must cite a source | Yes | Citations point at your documents, which a reader can check |
| Documents are stale or contradictory | No, until fixed | Retrieval returns old or conflicting passages, and the answer inherits the confusion |
| Chunking splits tables, lists or procedures | No, until fixed | The retrieved passage is missing the context that made it true |
| The question needs reasoning, not lookup | Partly | Retrieval supplies facts; the model still has to reason correctly, and can still err |
| No relevant document exists | No | The system should say it does not know, not invent an answer from near-misses |
The most important failure mode is the quiet one: retrieval returns passages that look relevant but are not quite right — a similar product, an older policy, a different customer’s terms — and the model writes a confident answer from them. This is why production RAG systems add safeguards: a similarity threshold below which the system says it does not know, a rule that the answer must stay within the retrieved text, and evaluation against a set of known questions with known answers, run before every update.
Build vs buy: a simple outline
Buy when you need an answer this month: a hosted RAG product, a document Q&A feature in a tool you already use, or a managed search service. You trade control for speed, and you accept the vendor’s chunking, embedding and retrieval choices. Check how it handles access control, index freshness and citation quality before you commit, because those three are hard to retrofit.
Build when your documents, access rules or evaluation needs are unusual: strict permission boundaries, specialised document formats, or a need to measure retrieval quality precisely. Building means owning the pipeline above — ingestion, chunking, embedding, storage, retrieval, generation — and owning its evaluation. The build cost is not the first demo; it is the months of tuning chunking and retrieval that follow it.
A sensible middle path is to prototype with a hosted tool on a small, well-understood document set, measure how often the answers are right and properly cited, and only invest in building when the prototype shows you exactly which part needs custom work. Most teams that skip the prototype end up building a system whose failure they have not yet understood.
For the broader picture of how agents use retrieved knowledge, see what AI agents are and how they work, and for a beginner-friendly starting point, see AI tutorials for beginners. For how governed enterprise systems handle agent actions, see the OpenAI–ServiceNow partnership.
Limitations
This article explains RAG from public documentation and guides; it is not a benchmark of any RAG product, and no accuracy or retrieval-quality figure is claimed, because such figures depend entirely on the document set and the evaluation method. Chunk-size figures cited are typical ranges from guides, not a universal recommendation. If you build or buy a RAG system, evaluate it on your own documents and questions before trusting its answers.